How Reducto launched Deep Extract on X
Turn documents into data. Build without constraints.
What Reducto launched

Today, we’re setting the new standard for complex document extraction. Introducing Deep Extract. It utilizes an agent harness approach that repeatedly iterates and verifies outputs until they are at human-level accuracy. More below: https://t.co/dVtsAqDozA
How TLVC rated the launch
TLVC Rating
About the launch
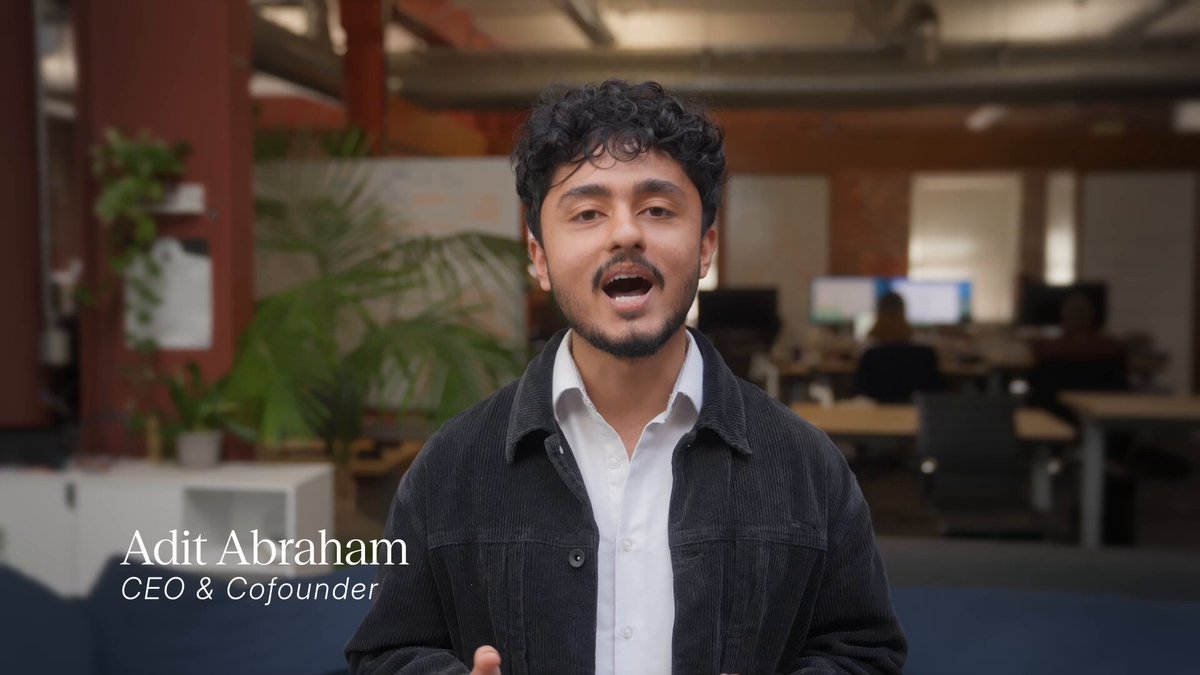
Deep Extract is a new setting on Reducto's extraction API for teams that need complete structured fields from long documents. It runs an agent loop that extracts values, verifies them against the source, and re-extracts until the output meets a quality threshold the caller can define in a prompt, such as requiring invoice line items to sum to the stated total. Sub-agents split the work so the loop can continue across thousands of rows on documents that run to hundreds of pages. The launch is aimed at invoice line items, brokerage statement transactions, and equipment manifests, the kinds of lists where a single model pass often drops entries and a person still has to review the result. Reducto, co-founded by Adit Abraham and Raunak Chowdhuri, converts PDFs, scans, spreadsheets, slides, and handwriting into structured data for AI teams and document-heavy enterprises, including Harvey, Scale AI, and Vanta. In production beta, the company says Deep Extract handled documents up to 2,500 pages and extracted more than 28 million fields, with some customers moving from 10 to 20 percent field accuracy on frontier models to 99 to 100 percent. With citations enabled, each field includes a bounding box on the source page. The setting is available now on the Extract endpoint.
Tags
Questions
Frequently asked questions
The Reducto launch post reached 102K views on X, with 423 likes, 28 reposts, 38 comments, 437 bookmarks.
Reducto launched on X on April 6, 2026 with the message "Turn documents into data. Build without constraints.".
Deep Extract is a new setting on Reducto's extraction API for teams that need complete structured fields from long documents.
Launchvideo.com rated the Reducto launch 4.00 out of 5.