How Turbopuffer announced smarter products need reachable data on X
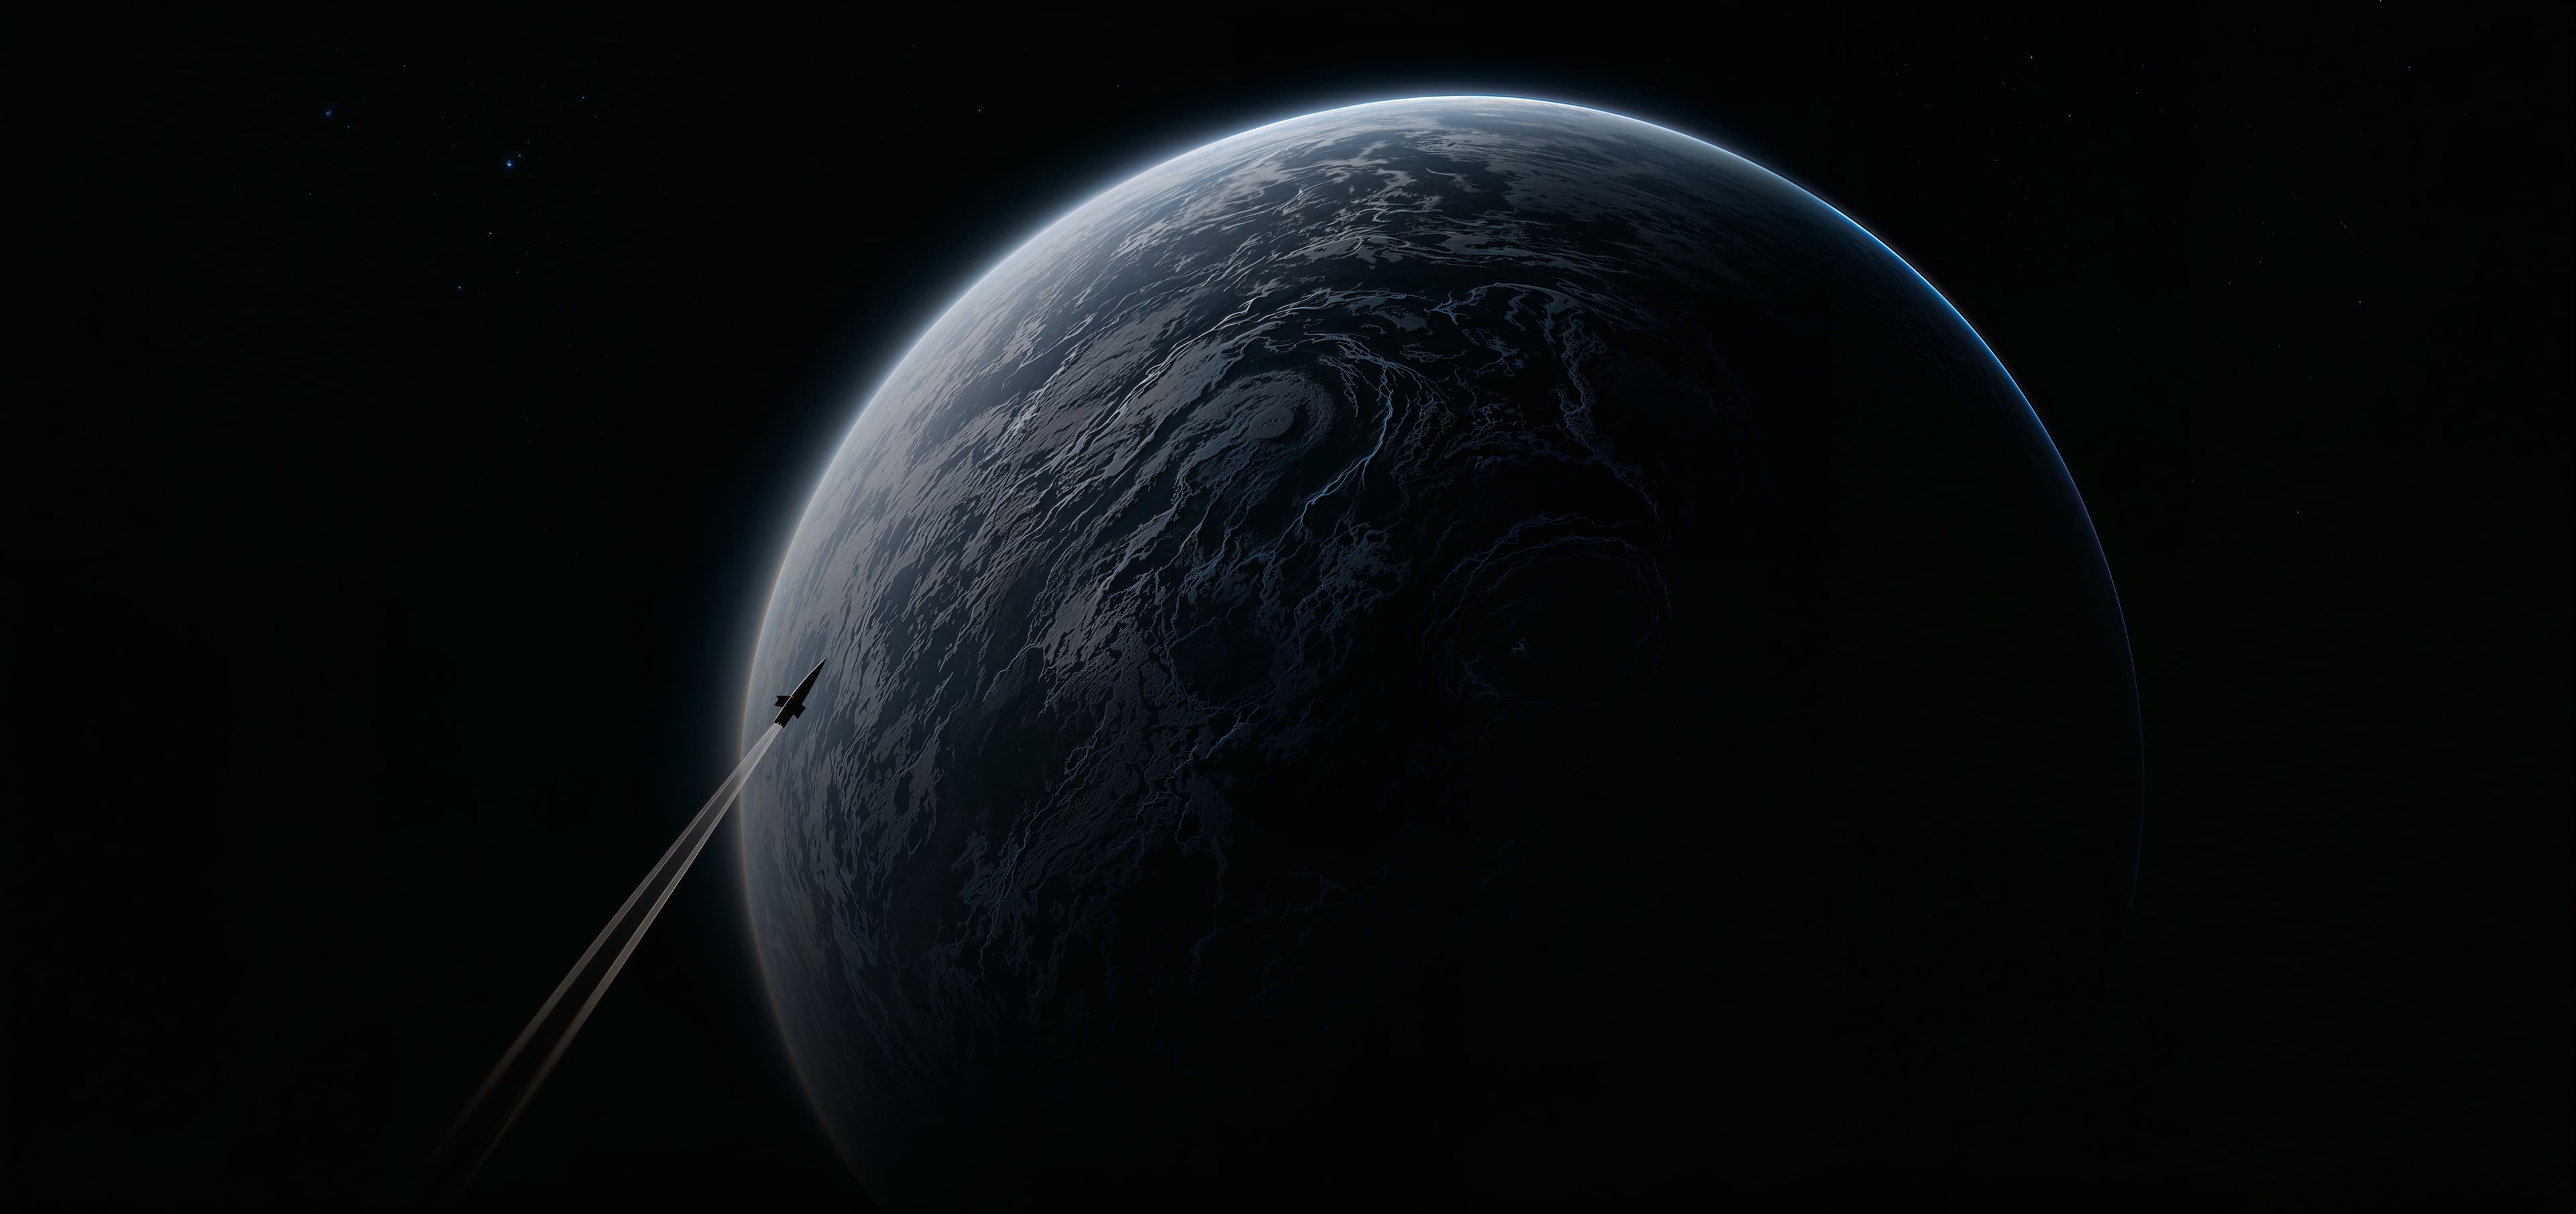
search every byte
What Turbopuffer launched

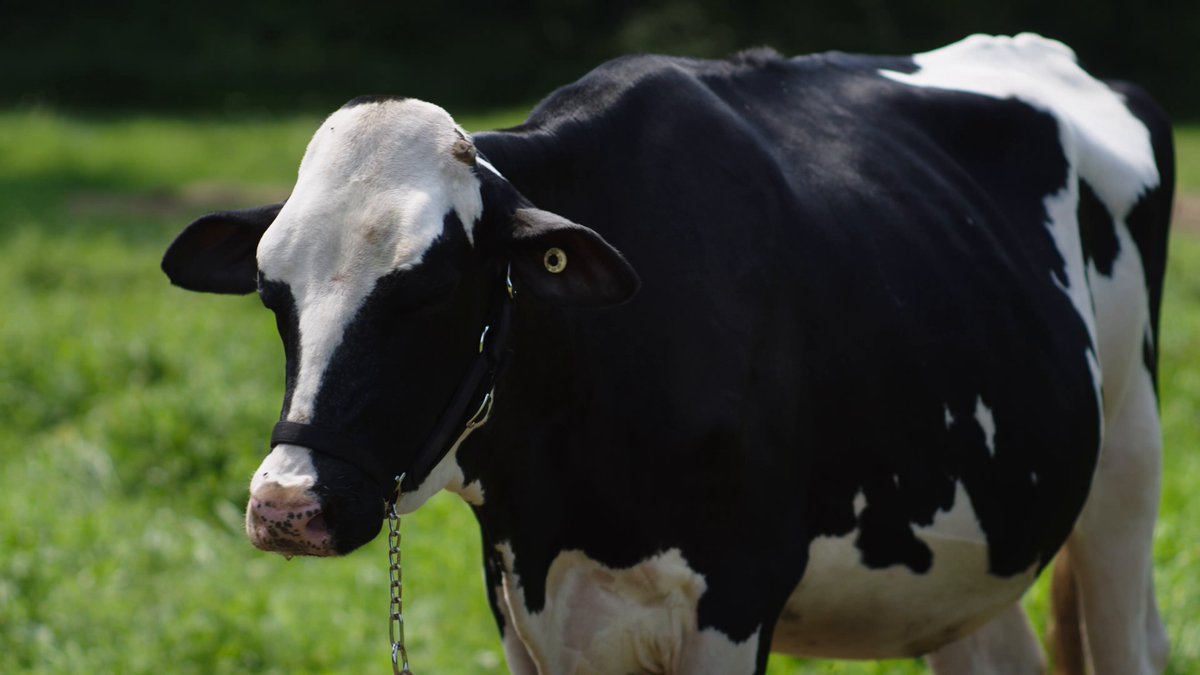
your product is only as smart as the data it can reach. make your product smart. unleash your cow. https://t.co/Uck61X5XIW
How TLVC rated the launch
TLVC Rating
About the launch
Turbopuffer is a serverless search engine that combines vector and full-text search on top of cloud object storage, aimed at teams building AI products that need to retrieve context from very large corpora without paying to keep every index hot in RAM. It was co-founded by Simon Hørup Eskildsen and Justine Li, who met at Shopify while scaling its infrastructure , and it now sits behind retrieval in products like Cursor, Notion, Linear, and Superhuman . The pitch behind this "search every byte" launch is straightforward: an AI product is only as useful as the data it can actually reach at query time, and most stacks quietly cap that surface because keeping petabytes searchable is either too slow or too expensive. The architectural bet is to store data durably in object storage (S3, GCS, or Azure Blob) and pull it into NVMe SSD cache or RAM only when queried , which Google Cloud describes as roughly 90% cheaper than traditional approaches . That tradeoff is what makes "search all your data" plausible for workloads that would otherwise be pruned or sharded aggressively. On the Cursor deployment, unlimited namespaces let the infrastructure team stop manually balancing codebase indexes across servers , and Notion warms a namespace cache when a user opens the Q&A dialog so subsequent queries are fast , illustrating the two shapes of workload the system is tuned for. This launch matters right now because retrieval quality has become the visible ceiling on agent and copilot performance, and infra teams are re-evaluating first-generation vector databases on cost as usage scales into billions of vectors. Turbopuffer is positioning itself as the default retrieval layer for that transition, with production references ( the engine already hosts more than a trillion documents and serves tens of thousands of queries per second ) meant to reassure founders and operators that the object-storage approach holds up under real load.
Tags
Questions
Frequently asked questions
The Turbopuffer launch post reached 328K views on X, with 1.5K likes, 78 reposts, 82 comments, 657 bookmarks.
Turbopuffer launched on X on September 10, 2026 with the message "search every byte".
Turbopuffer is a serverless search engine that combines vector and full-text search on top of cloud object storage, aimed at teams building AI products that need to retrieve context from very large c.
Launchvideo.com rated the Turbopuffer launch 4.80 out of 5: hook 5/5, editing / creativity 5/5, copy 5/5, sentiment of launch 5/5, distribution strategy 4/5.