How Cerebellum Labs launched Cerebellum Labs on X
Hosts custom AI models billed per token instead of hourly GPU rental
What Cerebellum Labs launched

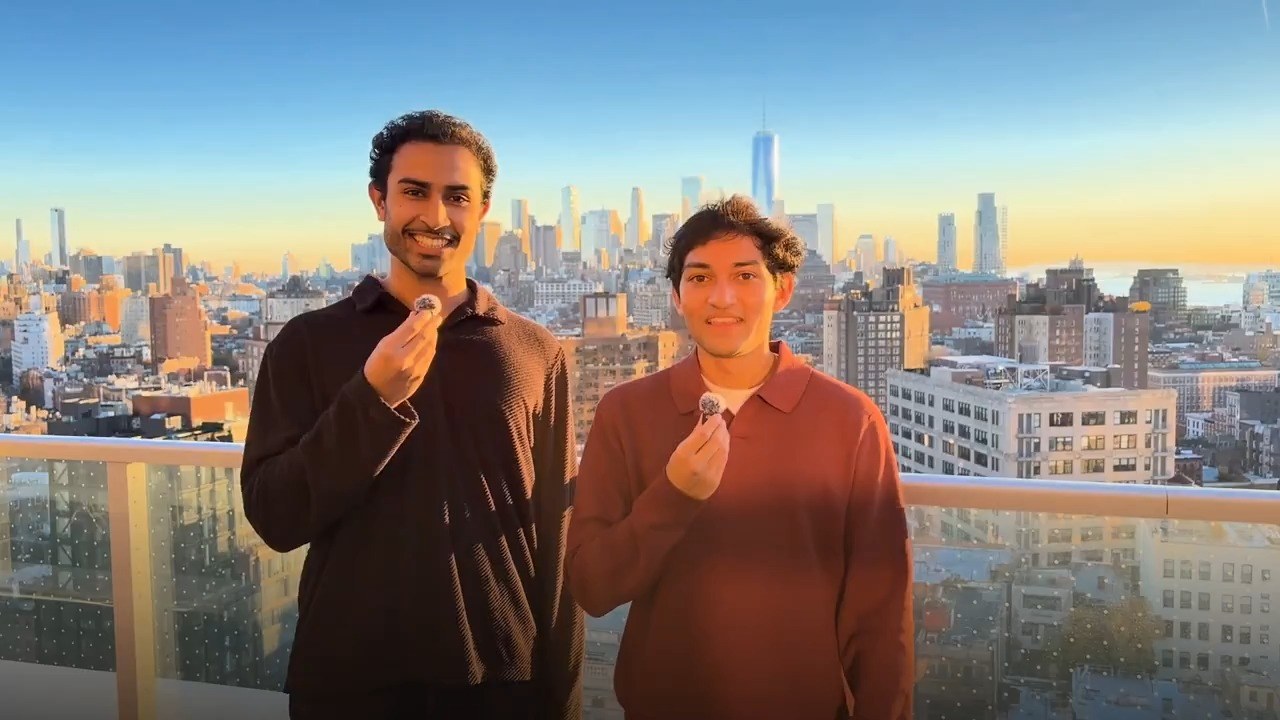
We believe every company should run its own custom models. But right now that means paying for a GPU by the hour. Today we’re launching Cerebellum Labs (YC W27). Custom models, priced per token. $25 in free credits to start: https://t.co/Rd8vMOYdgh https://t.co/MAjQqybEZd
Transcript
How LaunchVideo.com rated the launch
LaunchVideo.com rating
How the launch performed
- 77K
- views on X
- #1106
- of 1658 launches we track
- 0.4x
- the 212K median launch
What this launch shows
| Group | Views |
|---|---|
| Cerebellum Labs, this launch | 76,900 |
| Similar-sized accounts, median across 274 launches | 55,479 |
| AI infrastructure / MLOps / evals launches, median across 176 launches | 230,126 |
| Every launch, median across 1658 launches | 211,764 |
Cerebellum Labs reached 77K views, 0.4 times the directory median of 212K, ranking 1106 of 1658 launches we track. Among AI infrastructure / MLOps / evals launches it ranks 127 of 176, 0.3 times that group's median. The post came from an account with 497 followers and reached 155 times that many people, ranking 122 of 274 launches from accounts of a similar size.
Replies ran at 11.4 per 10,000 views, well above the 3.7 median. Conversation in the first hours is what the ranking model rewards with more reach. Bookmarks came in at 60.6 per 10,000 views against a median of 14.8. One bookmark for every 1.1 likes is a high ratio and usually means people intend to come back and try the product.
The launch video runs 1:39, against a directory median of 74 seconds. It went out on a Thursday.
More launches in its category
 Rayline: ARC by RaylineRoutes each request to the right AI model and thinking depth6.8M views
 ChatAndBuild: Living BrainOne persistent memory shared across ChatGPT, Claude, Cursor and custom agents6.3M views
 State MachinesTest your agent against enterprise APIs that work like the real ones.5.8M views
 EagleAI at blazing speed5.2M views
 You.comSearch and inference for AI4.4M views
About the launch
Cerebellum Labs is launching Cerebellum Cloud for teams that fine-tune their own models and still pay for a GPU by the hour, even when the model sits idle most of the day. You import open-weight text weights, a full fine-tune or a LoRA adapter, from a Hugging Face repo (private repos included) or an S3 or GCS link, confirm the detected size and price, and get an OpenAI-compatible endpoint and API key. Billing is per token from prepaid credits. Idle time, storage, and GPUs are not charged, and the model scales to zero when no requests arrive. Prices are grouped by size. A small model, up to about 14B parameters, costs $0.75 per million input tokens and $2.25 per million output tokens as a full fine-tune, or $0.25 and $0.75 as a LoRA on a listed base. Medium models, up to about 32B, are $1.50 and $4.50, or $0.50 and $1.50 for LoRA. A 70B model in FP8 is $2.50 and $7.50, or $1.00 and $3.00 for LoRA. Listed bases, including Llama 3.1 8B Instruct and several Qwen and Gemma checkpoints, deploy right away. LoRA adapters need one of those bases. Full fine-tunes and merges of other bases go live in minutes. Weights with custom code or pre-quantized formats are reviewed first, and nothing is charged until the model is live. New accounts start with $25 in credits that do not expire. Prompts and outputs are not stored or used for training. The launch comes from Sahil Mahendrakar, previously at AWS and a Columbia '24 graduate, who is building the company with Suhaas Katikaneni and announced it as a YC W27 company. The product targets the gap where custom models are common enough to matter and still awkward to serve: a dedicated GPU billed around the clock for a workload that might run only minutes a day, or a scale-to-zero setup that stalls on cold starts. Cerebellum Cloud loads weights on demand. The first request after a quiet period waits while the model starts instead of failing, and the stack uses multi-LoRA serving, model swapping, and GPU routing so low or bursty traffic does not need a reserved GPU.
Tags
Questions
Frequently asked questions
The Cerebellum Labs launch post reached 77K views on X, with 515 likes, 37 reposts, 88 comments, 466 bookmarks.
Cerebellum Labs launched on X on November 19, 2026 with the message "Hosts custom AI models billed per token instead of hourly GPU rental".
Cerebellum Labs is launching Cerebellum Cloud for teams that fine-tune their own models and still pay for a GPU by the hour, even when the model sits idle most of the day.
LaunchVideo.com rated the Cerebellum Labs launch 2.60 out of 5: hook 2/5, editing / creativity 2/5, copy 4/5, sentiment of launch 4/5, distribution strategy 1/5.